DSCI 512 Lecture 1 : Introduction and Time Complexity

Sky (Kehan) Sheng

Meet your instructor

  • Sky (Kehan) Sheng, PhD
  • My research bridges AI fairness, animal welfare and data science.
  • Contact
    • 📧: skysheng@cs.ubc.ca
    • 💼: ICCS Building Room 187
    • 💬: @Sky on Slack
    • 🕰️ MDS calendar for office hours.

DSCI 512 overall learning objectives

  • Fundamental data structures and algorithms
  • Complexity analysis (time complexity and space complexity)
  • Techniques for improving Python code performance.

Course structure

  • Lecture notes is a good starting point for you to review the material in advance.
  • There are some recommended readings/videos for you to review in advance.
  • TA will host weekly review sessions on Friday or Monday, please check out MDS calendar.
  • The course is extremely compressed of a “classic” undergraduate course on algorithms and data structures.
  • We will use Python.
  • Lectures in this section are being recorded, for personal study only as requested by the Centre for Accessibility. The recordings will not be posted or shared.

Grading breakdown

Note

In-person attendence for lab quiz is mandatory.

Assessment Weight
Lab 1 9%
Lab 2 9%
Lab 3 9%
Lab 4 9%
Lab Live Coding Quiz (Week 1) 4%
Lab Live Coding Quiz (Week 2) 4%
Lab Take-home Coding Quiz (Week 3) 2%
Lab Live Coding + Reasoning Quiz (Week 4) 4%
Quiz 1 25%
Quiz 2 25%

iClicker Set Up for Section 002

join.iclicker.com/AGFP

What is an algorithm?

What is an algorithm? Really.

  • An algorithm is a well-defined computational procedure designed to solve a problem.
  • provides a sequence of precise steps for transforming input into output in order to arrive at a solution.

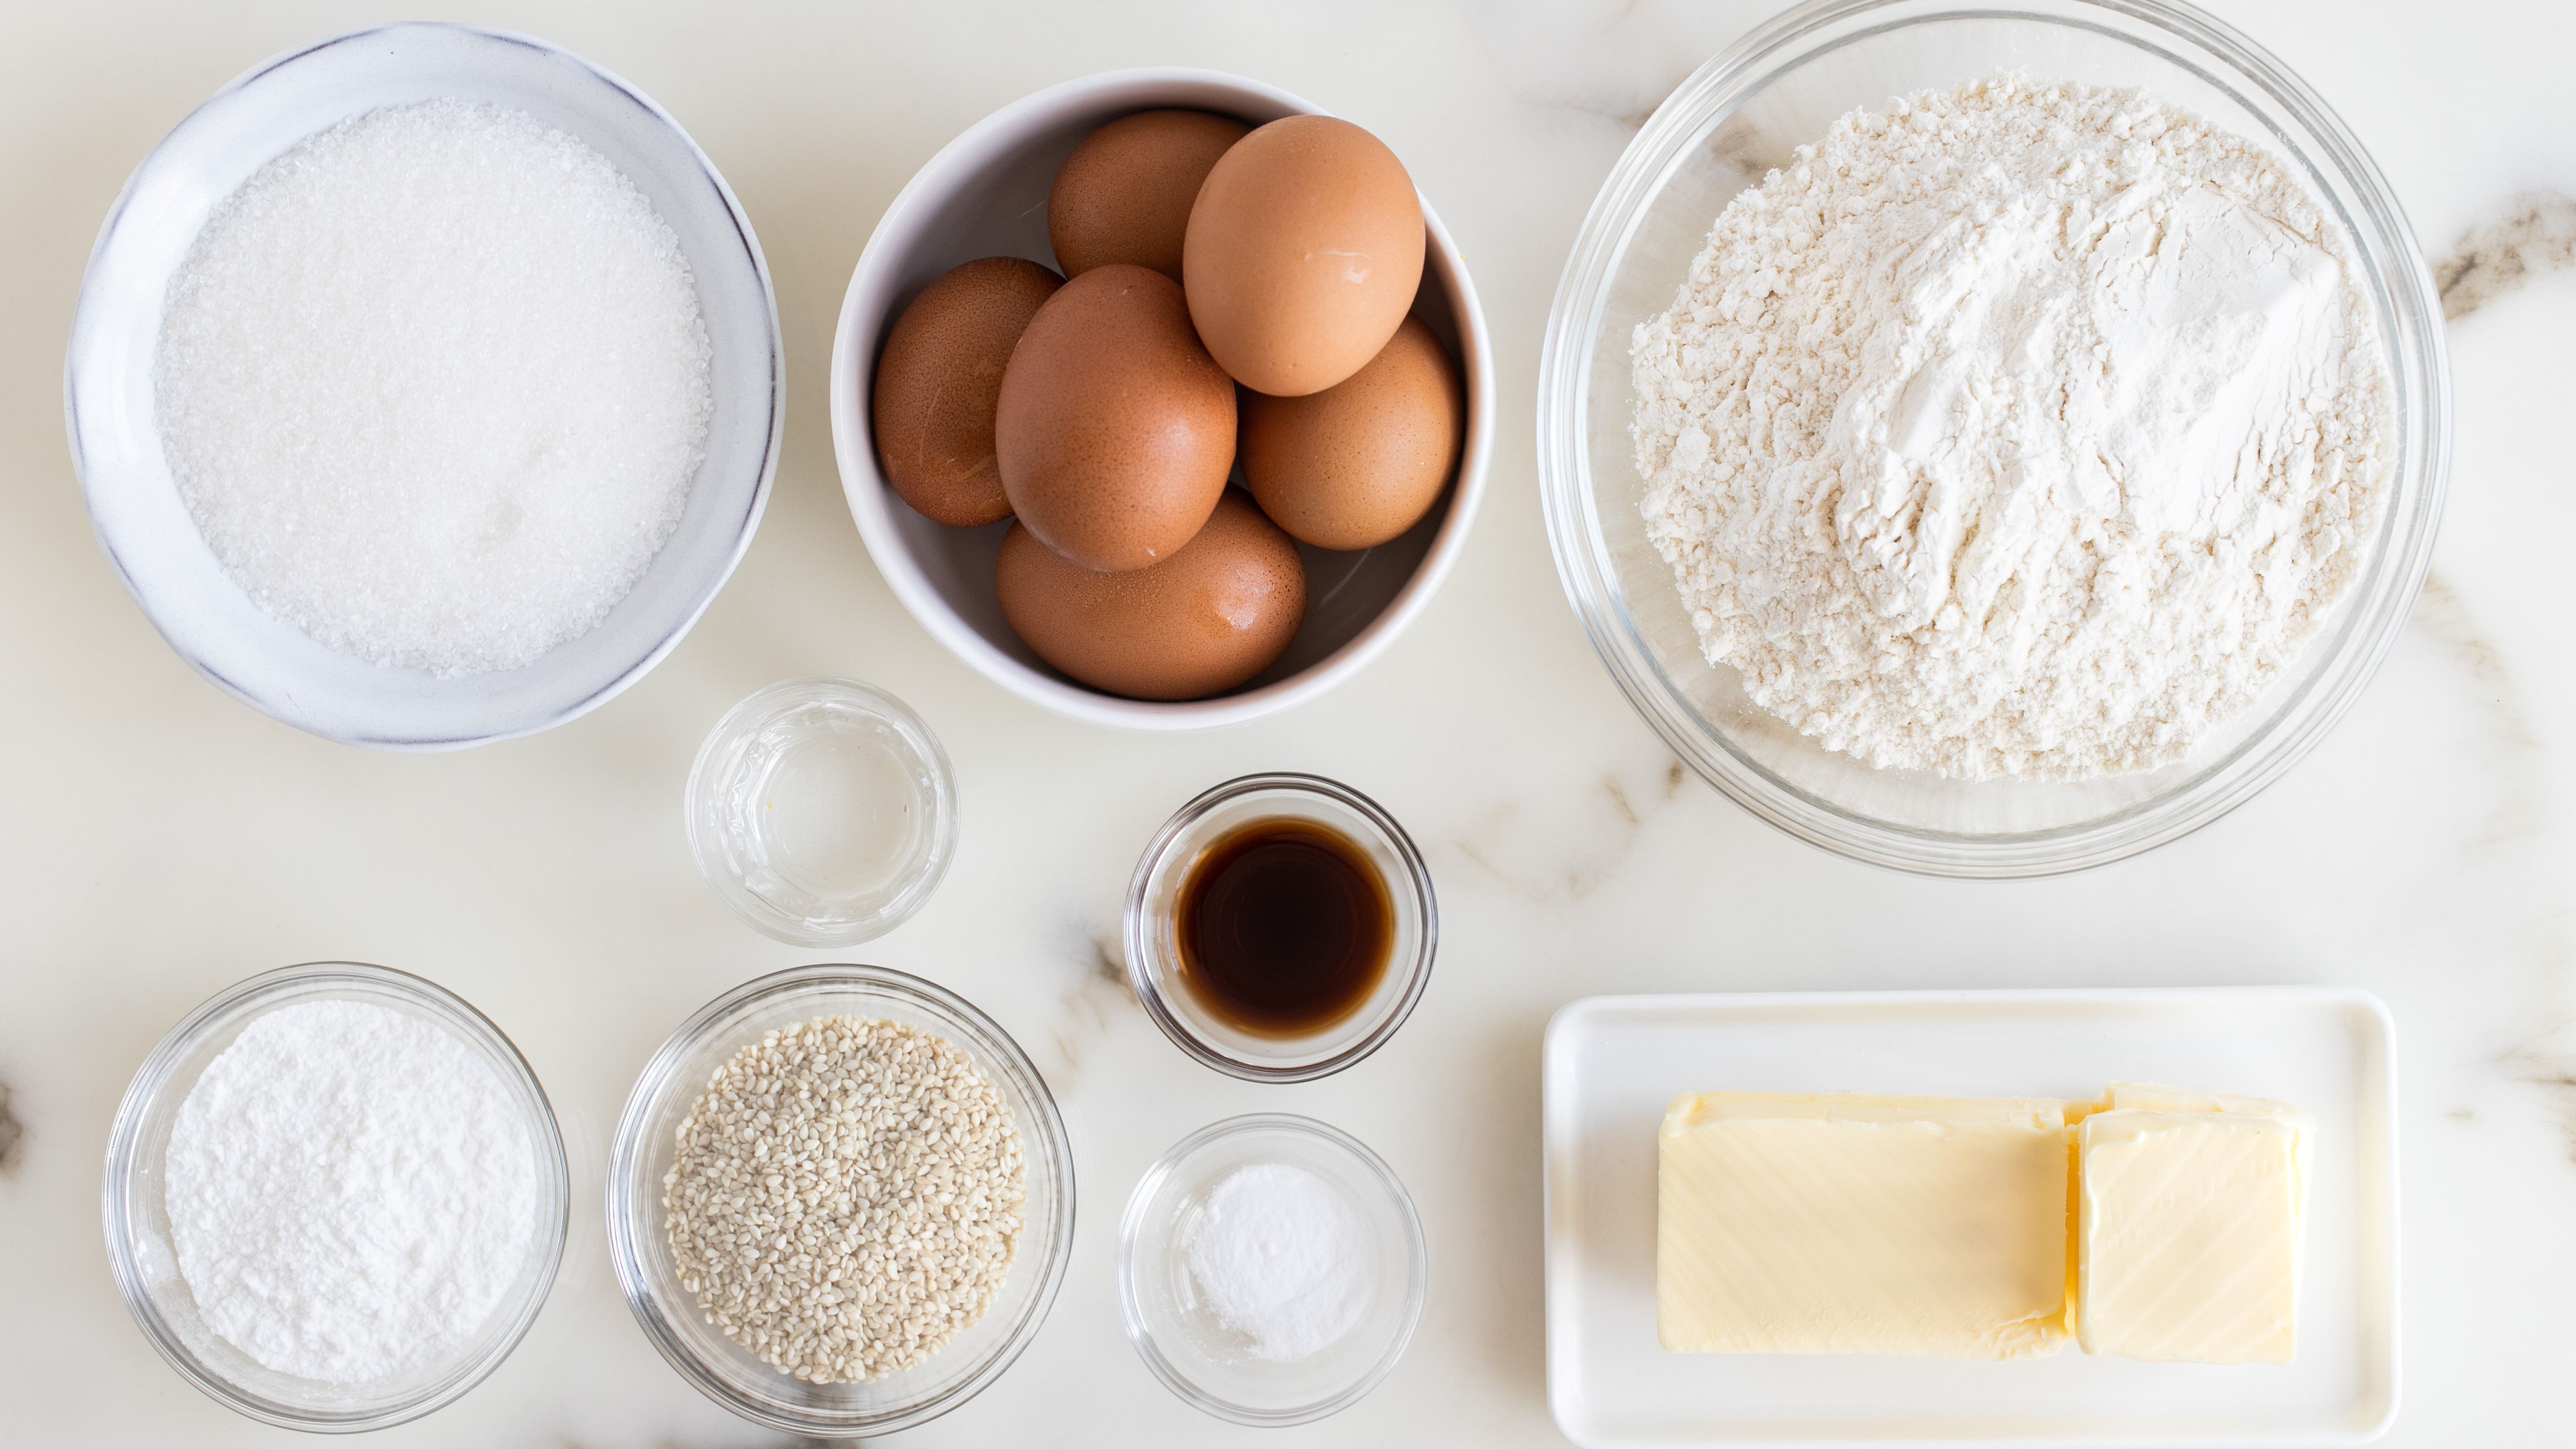
Ingredients ≈ input

Recipe ≈ algorithm

What is a data structure?

  • A data structure is a way to organize and manage data.

Challenges Past Students Have Faced in This Course

  • Difficulty/pace
  • Python coding
  • Some topics did not seem relevant to data science/AI

iClicker: Do we still need to learn algorithms and data structures in the AI era?

(A) YES! AI can’t replace my brain!

(B) NO! My bestie ChatGPT knows it all!

(C) Strategically indecisive: “It depends…”

(D) I’m still figuring out what data science is…

Why learn algorithms and data structures in the AI era?

There is no shortcut to learning how to think

AI updates every 6 months, but algorithmic fundamentals don’t go out of fashion

DSCI 512: Absolute fundamentals a data scientist needs to know

AI evaluation (AI eval) is a fancier term for data science

Outline of Today’s Lecture

  • Course overview ✅
  • 🚗 Today’s story: how does Uber find you a ride?
  • ⏱️ Code profiling: measure where the time goes
  • 📈 Time complexity: predict how the time grows with \(n\)

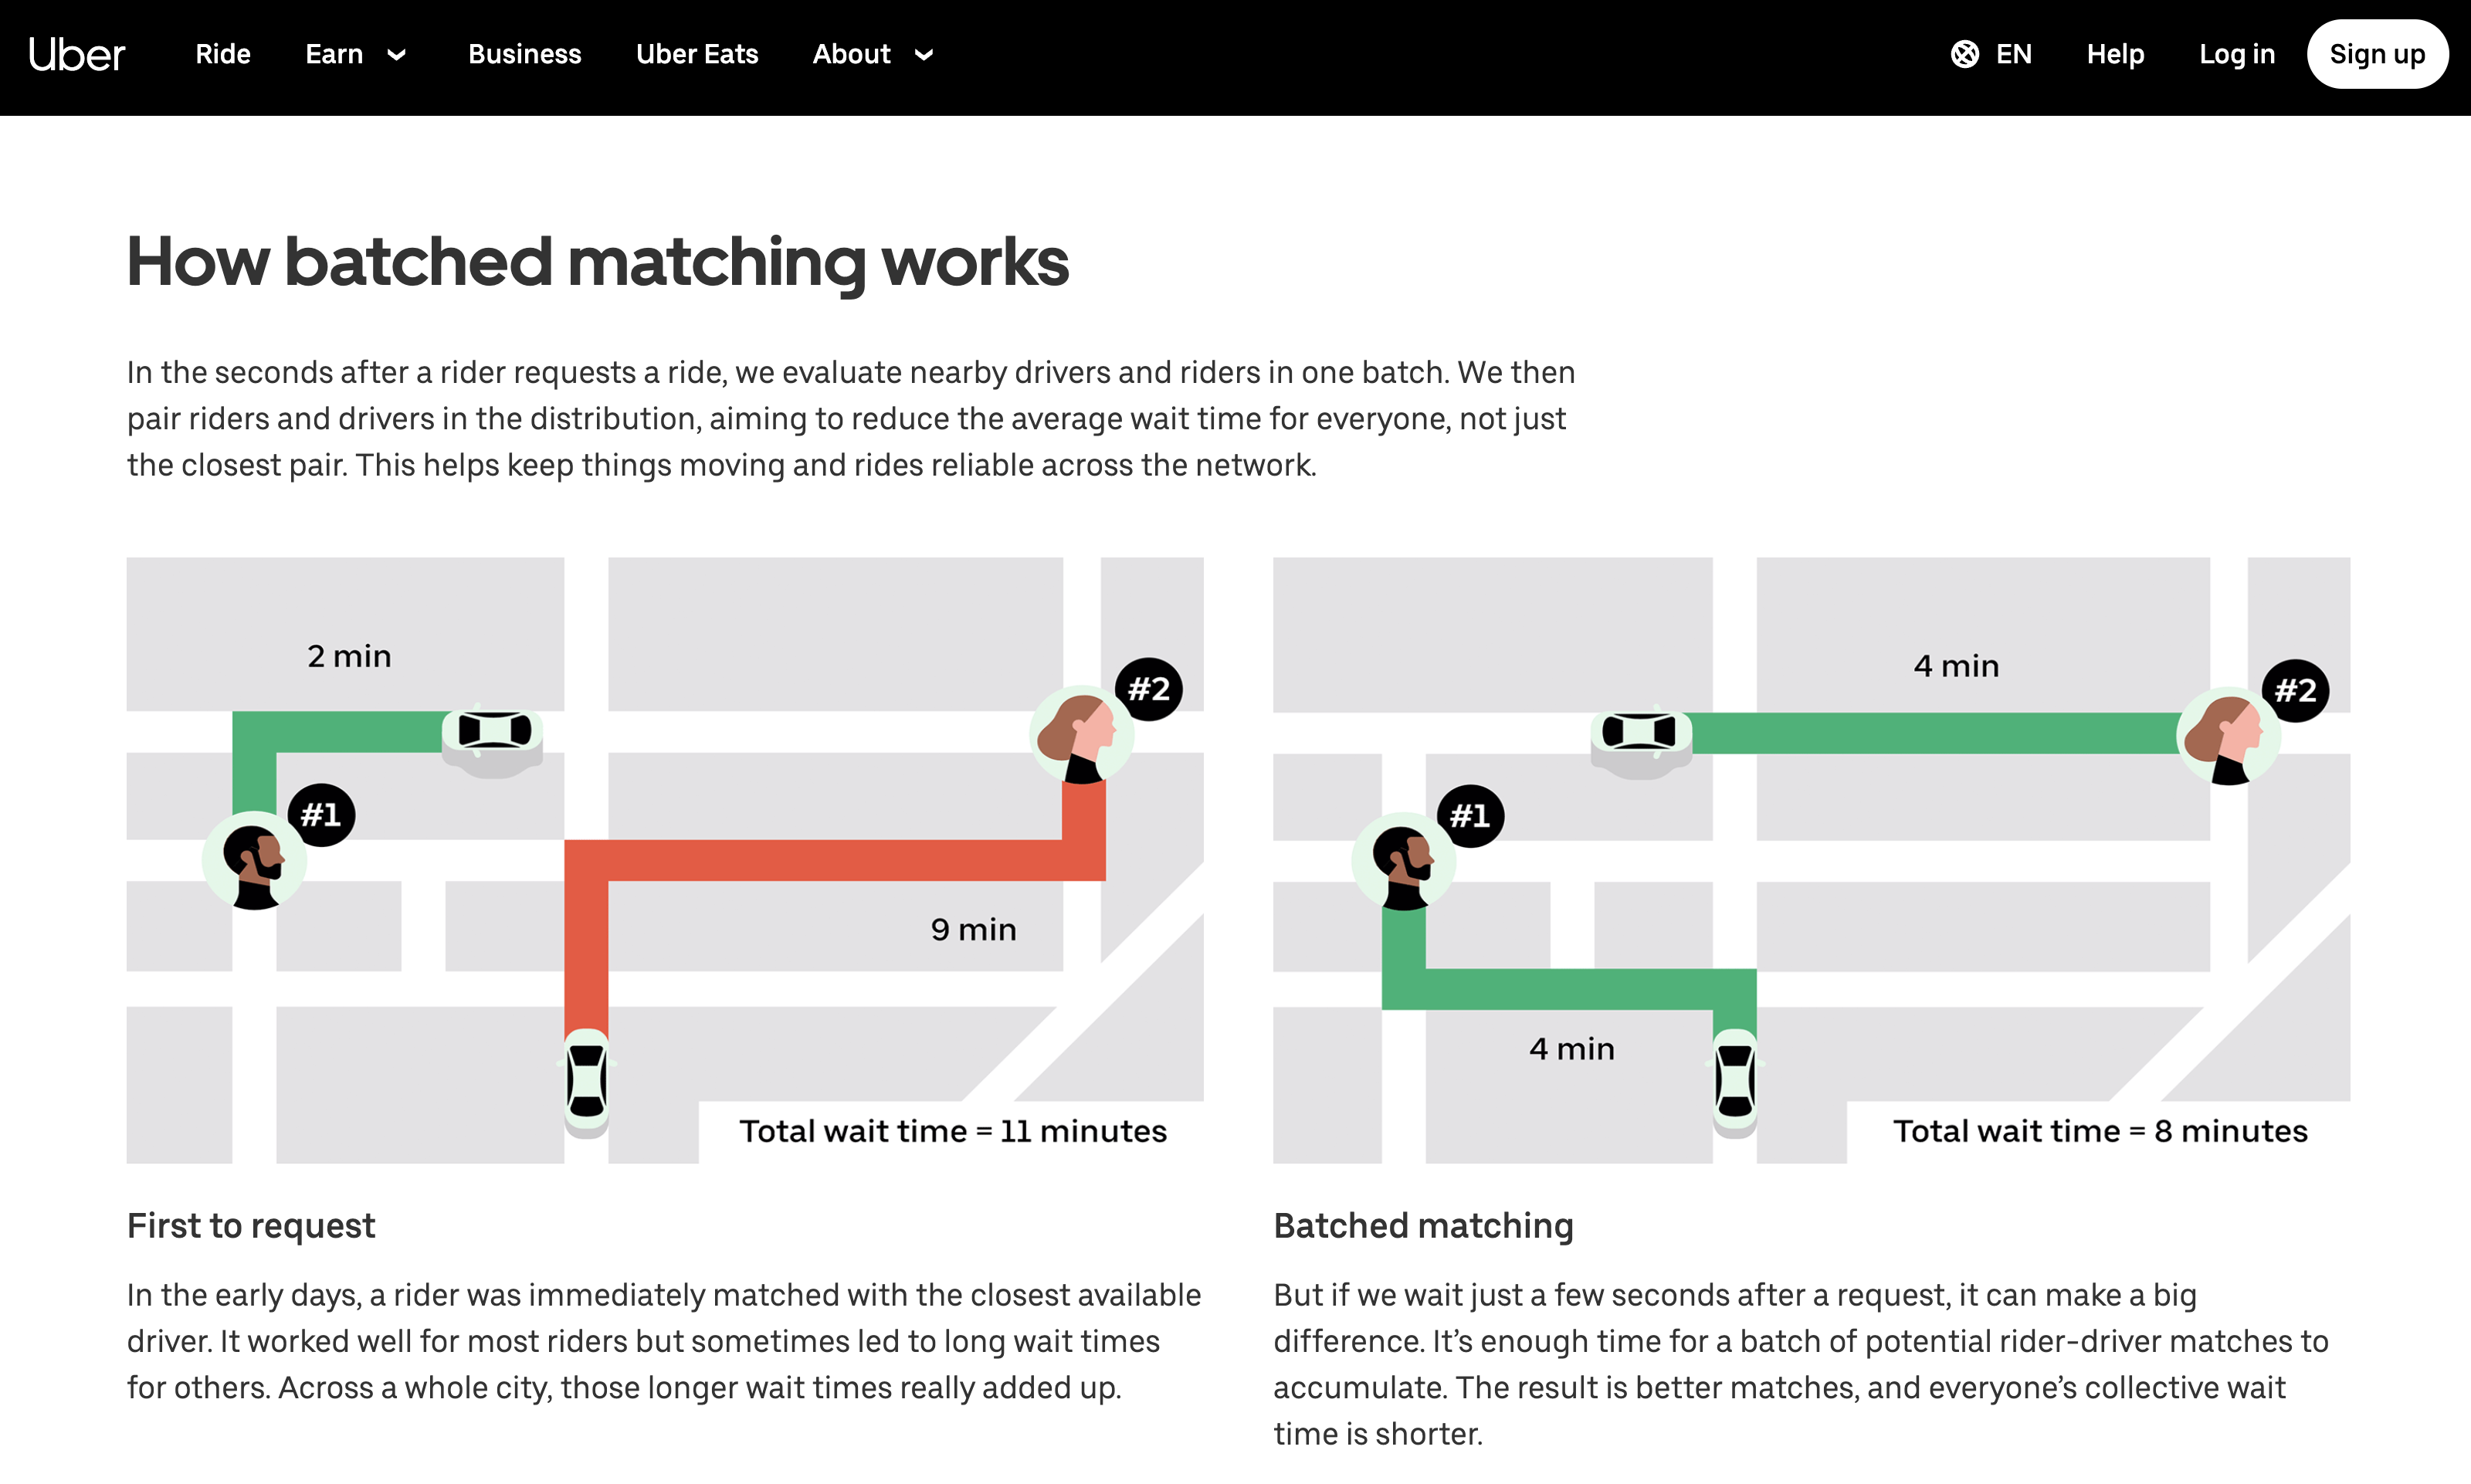
🚗 Today’s story: how does Uber find you a ride in seconds?

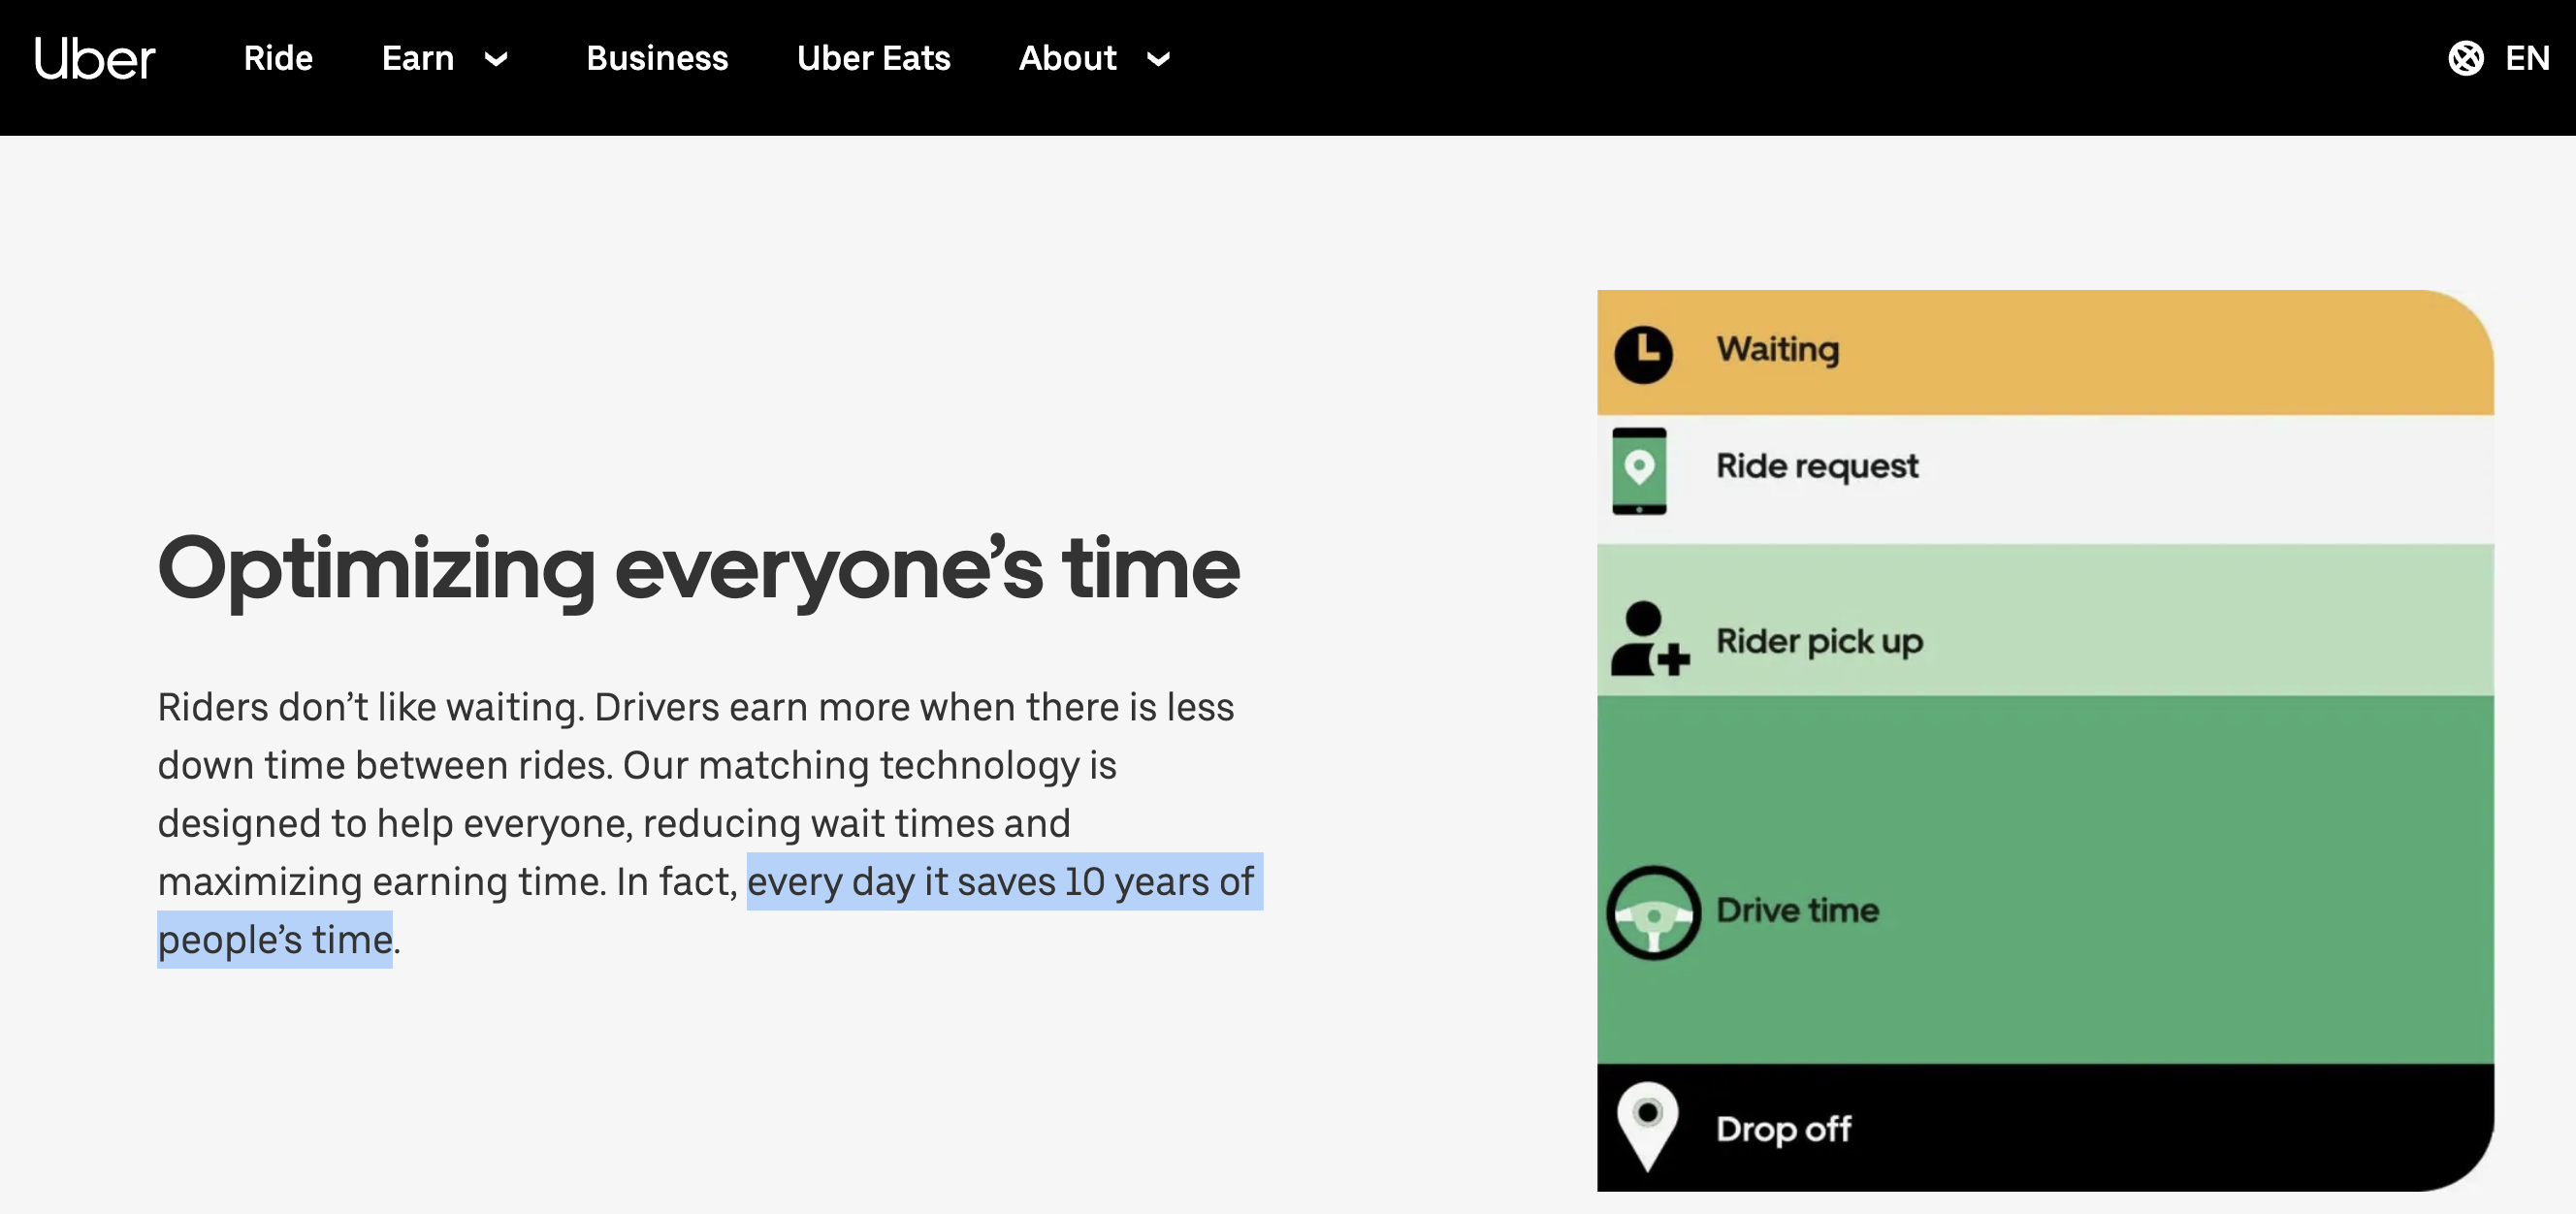
🚗 Uber’s promise: optimizing everyone’s time

🚗 A better algorithm, not a faster computer

🚗 Today, you are Uber’s first data scientist

2010, Vancouver

🚕 🚕 🚕 🚕 🚕 🚕 🚕 🚕 🚕 🚕

\(n = 10\) drivers

Any code works.

Today

🚕 × millions of drivers, billions of trips a year

\(n = 10{,}000{,}000\)

Does your code still work?

The question of the day: if \(n\) (drivers, riders, requests) grows from 10 to 10 million, what happens to the runtime of my code?

  • ⏱️ Code profiling: measure it.
  • 📈 Time complexity: predict it, before Uber gets big.

⏱️ Code Profiling

Measure where your code spends its time.

🚗 Scenario 1: does this rider already have an account?

A rider opens the app and logs in. Before anything else, Uber checks: is this rider already in our system, or do we show the sign-up page?

n = 10_000_000                    # 10 million riders (the _ does not change the value, it's for readability)
rider_accounts = list(range(n))   # account IDs of every registered rider: 0, 1, ..., 9_999_999
new_rider = -1                    # someone opening the app for the first time: no account yet
new_rider in rider_accounts       # does this rider already have an account?
False

False → show the sign-up page. But to say False, Python had to compare -1 with all 10 million IDs.

⏱️ timeit: search in a list vs. a set

Look up the new rider in a list of 10 million accounts:

import timeit
rider_accounts = list(range(n))
seconds = timeit.timeit("new_rider in rider_accounts", number=10, globals=globals())  # total for 10 runs
print(f"{seconds / 10 * 1e3:.1f} ms per lookup")
70.8 ms per lookup

Look up the new rider in a set of 10 million accounts:

rider_accounts = set(range(n))
seconds = timeit.timeit("new_rider in rider_accounts", number=1_000_000, globals=globals())  # total for 1 million runs
print(f"{seconds / 1_000_000 * 1e9:.1f} ns per lookup")
18.5 ns per lookup

1 ms = 1,000,000 ns. Same question, same riders, different data structure.

⏱️ But building the collection costs time too

Time to build the list of 10 million account IDs:

seconds = timeit.timeit("list(range(n))", number=1, globals=globals())  # build it once
print(f"{seconds * 1e3:.0f} ms to build the list")
371 ms to build the list

Time to build the set of 10 million account IDs:

seconds = timeit.timeit("set(range(n))", number=1, globals=globals())  # build it once
print(f"{seconds * 1e3:.0f} ms to build the set")
477 ms to build the set

The set is slower to build but much faster to search. So which one wins over a whole day of logins?

🚗 Build once, look up all day: who wins?

Total time = time to build the collection + (number of logins) × time per lookup, using the numbers we just measured.

🚗 Scenario 2: notify the nearby drivers

A rider requests a ride. The app sends a push notification to each of the \(n\) nearby drivers.

def notify_drivers(n):
    for driver in range(n):
        time.sleep(0.1)  # 0.1 s each for push notification

cProfile tells us how much time was spent in each function:

import cProfile
cProfile.run("notify_drivers(5)", sort="cumulative")
         9 function calls in 0.501 seconds

   Ordered by: cumulative time

   ncalls  tottime  percall  cumtime  percall filename:lineno(function)
        1    0.000    0.000    0.501    0.501 {built-in method builtins.exec}
        1    0.000    0.000    0.501    0.501 <string>:1(<module>)
        1    0.000    0.000    0.501    0.501 1030441696.py:1(notify_drivers)
        5    0.501    0.100    0.501    0.100 {built-in method time.sleep}
        1    0.000    0.000    0.000    0.000 {method 'disable' of '_lsprof.Profiler' objects}

column what it means
ncalls how many times the function was called (time.sleep: 5)
tottime time spent inside the function only, not counting the functions it called
percall (first) tottime / ncalls, one call on its own (time.sleep: 0.501 / 5 ≈ 0.100 s)
cumtime time in the function plus everything it called
percall (second) cumtime / ncalls

We expect 5 × 0.1 s ≈ 0.5 s. Reading our rows:

  • builtins.exec, <module>, notify_drivers: cumtime 0.501 but tottime 0.000. They are wrappers: all their time is spent in what they called.
  • time.sleep: 5 calls, tottime 0.501. This is where the time goes, the row to fix.

⏱️ LineProfiler: profile line by line

def notify_drivers(n):
    for driver in range(n):
        time.sleep(0.1)  # 0.1 s each

The LineProfiler class from the line_profiler library shows the time on each line:

lp = LineProfiler()
lp.add_function(notify_drivers)
lp.runcall(notify_drivers, 5)
lp.print_stats()
Timer unit: 1e-09 s

Total time: 0.501366 s
File: /tmp/ipykernel_2358/830238303.py
Function: notify_drivers at line 1

Line #      Hits         Time  Per Hit   % Time  Line Contents
==============================================================
     1                                           def notify_drivers(n):
     2         6      17135.0   2855.8      0.0      for driver in range(n):
     3         5  501349029.0    1e+08    100.0          time.sleep(0.1)  # 0.1 s each

🚗 Twice as many drivers: \(n = 10\)

lp = LineProfiler()
lp.add_function(notify_drivers)
lp.runcall(notify_drivers, 10)
lp.print_stats()
Timer unit: 1e-09 s

Total time: 1.0012 s
File: /tmp/ipykernel_2358/830238303.py
Function: notify_drivers at line 1

Line #      Hits         Time  Per Hit   % Time  Line Contents
==============================================================
     1                                           def notify_drivers(n):
     2        11      29982.0   2725.6      0.0      for driver in range(n):
     3        10 1001171521.0    1e+08    100.0          time.sleep(0.1)  # 0.1 s each

Double the drivers → double the runtime.

🚗 Scenario 3: match every rider with every driver

Uber collects a batch of \(n\) riders and \(n\) drivers. For every rider, it estimates the pickup time from every driver.

🤔 How long would it take to match 5 riders with 5 drivers?

def match_riders(n):
    for rider in range(n):
        for driver in range(n):
            time.sleep(0.1)  # 0.1 s each
lp = LineProfiler()
lp.add_function(match_riders)
lp.runcall(match_riders, 5)
lp.print_stats()
Timer unit: 1e-09 s

Total time: 2.50309 s
File: /tmp/ipykernel_2358/2699516187.py
Function: match_riders at line 1

Line #      Hits         Time  Per Hit   % Time  Line Contents
==============================================================
     1                                           def match_riders(n):
     2         6       6348.0   1058.0      0.0      for rider in range(n):
     3        30      79927.0   2664.2      0.0          for driver in range(n):
     4        25 2503004614.0    1e+08    100.0              time.sleep(0.1)  # 0.1 s each

🚗 Double the batch: \(n = 10\)

🤔 How long does it take if we double the number of riders and drivers?

lp = LineProfiler()
lp.add_function(match_riders)
lp.runcall(match_riders, 10)
lp.print_stats()
Timer unit: 1e-09 s

Total time: 10.0124 s
File: /tmp/ipykernel_2358/2699516187.py
Function: match_riders at line 1

Line #      Hits         Time  Per Hit   % Time  Line Contents
==============================================================
     1                                           def match_riders(n):
     2        11      10434.0    948.5      0.0      for rider in range(n):
     3       110     300382.0   2730.7      0.0          for driver in range(n):
     4       100        1e+10    1e+08    100.0              time.sleep(0.1)  # 0.1 s each

One loop: double \(n\) → 2× the time.

Nested loop: double \(n\) → 4× the time.

🚗 Same \(n = 5\), each estimate twice as slow

🤔 When we get slow network, the communication time doubles, how long does it take now?

def match_riders_slow(n):
    for rider in range(n):
        for driver in range(n):
            time.sleep(0.2)  # now 0.2 s each

lp = LineProfiler()
lp.add_function(match_riders_slow)
lp.runcall(match_riders_slow, 5)
lp.print_stats()
Timer unit: 1e-09 s

Total time: 5.0031 s
File: /tmp/ipykernel_2358/2699578360.py
Function: match_riders_slow at line 1

Line #      Hits         Time  Per Hit   % Time  Line Contents
==============================================================
     1                                           def match_riders_slow(n):
     2         6       8573.0   1428.8      0.0      for rider in range(n):
     3        30      85967.0   2865.6      0.0          for driver in range(n):
     4        25 5003008577.0    2e+08    100.0              time.sleep(0.2)  # now 0.2 s each

🚗 How does runtime changes?

  • Each step twice as slow → runtime 2× (2.5 s → 5 s). A constant factor.
  • Twice as many riders and drivers → runtime 4× (2.5 s → 10 s). Growth with \(n\).
  • Big O notation (next section) cares about the second kind, not the first.

📈 Time Complexity

Predict how the runtime grows as \(n\) gets bigger, before Uber gets big.

📈 The experiment: run both for \(n = 1, 2, \dots, 30\)

Same two Uber functions, but each step now takes 1 ms instead of 0.1 s so we can try many values of \(n\).

def notify_drivers_1ms(n):
    for driver in range(n):
        time.sleep(0.001)

def match_riders_1ms(n):
    for rider in range(n):
        for driver in range(n):
            time.sleep(0.001)

📈 Drag \(n\) and watch the runtime grow

📈 Big O notation

  • Time complexity is commonly written with big O notation, which measures the approximate number of steps an algorithm performs as a function of the input size \(n\).
  • Big O notation only cares about how fast it grows as \(n\) gets larger.
Uber function steps big O name
notify_drivers(n): one loop \(n\) \(O(n)\) linear
match_riders(n): nested loop \(n \times n\) \(O(n^2)\) quadratic
  • Definition (optional): \(f(n)\) is \(O(g(n))\) if there is a positive number \(M\) such that \[f(n) \leq M\, g(n) \text{ for all large enough } n.\]

📈 The doubling rule

Big O name double \(n\) → runtime
\(O(1)\) constant same
\(O(\log n)\) logarithmic + a constant
\(O(n)\) linear 2×
\(O(n \log n)\) linearithmic a bit more than 2×
\(O(n^2)\) quadratic 4×
\(O(n^3)\) cubic 8×
\(O(n^k)\) polynomial \(2^k\)×
\(O(2^n)\) exponential squared
  • Why 8× for \(n^3\): \(\dfrac{g(2n)}{g(n)} = \dfrac{(2n)^3}{n^3} = 8\).
  • Why “squared” for \(2^n\): \(g(2n) = 2^{2n} = (2^n)^2\).
  • ⚠️ Exponential is the worst! Adding just one rider already doubles it: \(\dfrac{2^{n+1}}{2^n} = 2\).
  • \[1 \;<\; \log n \;<\; n \;<\; n \log n \;<\; n^2 \;<\; n^3 \;<\; 2^n\]

📈 Pick the curves, zoom \(n\), flip to log-log

📈 Big O is asymptotic, keeps only the fastest-growing term

Imagine we have an algorithm that does these three things: [1] find the rider’s account by binary search in a sorted list (\(\log n\)), [2] notify \(n\) drivers(\(n\)), each notification takes 2 seconds and [3] the algorithm waits for 5 seconds before matching drivers with riders (\(5\)). The algorithm’s runtime is:

\[f(n) = \log n + 2n + 5 \quad\Longrightarrow\quad O(n)\]

  • We drop multiplicative constants: \(2n\) steps (notify every driver twice) is still \(O(n)\).
  • We drop lower-order terms and additive constants: \(\log n\) would be dropped because \(\log n\) grows slower than \(n\). \(5\) would be dropped because it is a constant.
  • ⚠️ Additive vs. multiplicative: \(n + \log n\)’s Big O notation is \(O(n)\), but \(n \cdot \log n\)’s Big O notation is \(O(n \log n)\).

📈 Visualization: \(n + \log n + 5\) is “just” \(O(n)\)

⚠️ When \(n\) is small, big O can mislead

You are given 2 algorithms by your colleague at Uber, algorithm A takes \(100\sqrt{n}\) steps, \(O(\sqrt{n})\), and algorithm B takes \(n\) steps, \(O(n)\). So we should always pick algorithm A, right?

🧮 Finding the complexity: count the loops

One ride batch = Scenario 3 (match) followed by Scenario 2 (notify):

Step 1: count the steps. Nested loop: \(n \times n \times k\). Second loop: \(n \times k\). So \(f(n) = k n^2 + k n\).

Step 2: drop constant factors and lower-order terms. \(k\) is a constant, \(n\) is lower order than \(n^2\), so \(f(n) = O(n^2)\).

See the steps: every dot is one step

🧮 Two variables: \(n\) riders and \(m\) drivers

At rush hour there are more riders than drivers; at 3 am, the reverse. Now the two counts differ:

The time complexity is \(O(nm + m) = O(nm)\).

  • \(nm + m = (n+1)m\), and we don’t distinguish \(n\) from \(n+1\).
  • If \(m = n\) (as many drivers as riders) it becomes \(O(n^2)\).
  • \(O(n^2 + n + m)\) is just \(O(n^2 + m)\): we can drop \(n\) (dominated by \(n^2\)) but not \(m\).
  • \(O(n^2 + nm + m)\) is \(O(n^2 + nm)\): we can’t drop either term, because we don’t know whether riders or drivers will dominate.

🚗 Today’s takeaways

  • 🔧 What affects runtime?
    • Data structures — e.g., set is faster to search than list.
    • Algorithms — does it take \(n\) steps, or \(2n\) or \(100000n\) steps? How complicated is each step?
    • Implementation — language (Python vs. C), libraries (NumPy), hardware, caching/parallelism.
  • ⏱️ Profiling measures where time goes (don’t guess, measure!)
    • timeit: time one line of expression.
    • cProfile: how much time in each function.
    • LineProfiler: how much time on each line.
  • 📈 Big O predicts how runtime grows as \(n\) increases
    • Count the loops, keep the fastest-growing term, ignore constant factors and lower-order terms.
    • Uber: one loop over \(n\) drivers → double \(n\) gives 2× the time (\(O(n)\)).
    • Uber: nested loop over \(n\) riders × \(n\) drivers → double \(n\) gives 4× the time (\(O(n^2)\)).
  • ⚠️ Constants matter when \(n\) is small → big O only tells you which algorithm wins eventually.

❓ Questions?

🎯 (Bonus Slide) Best, worst and average case

Back to Scenario 1: rider_id in rider_accounts when rider_accounts is a list. Python checks the IDs one by one, from the left.

  • Best case: the rider is first in the list: 1 comparison.
  • Worst case: the rider is last, or has no account yet (our new_rider): \(n\) comparisons.
  • Average case: somewhere in the middle: about \(n/2\) comparisons, still \(O(n)\).
  • In this course we generally mean the worst case, which for large \(n\) often has the same complexity as the average case anyway.

(Bonus Slide) iClicker: what is the time complexity of surge_pricing(n)?

  • (A) \(O(n)\)
  • (B) \(O(n^2)\)
  • (C) \(O(n^2 + n)\)
  • (D) \(O(n^3)\)

(Bonus Slide) 🔧 What else affects the runtime?

  • The implementation decides the constants and lower-order terms (0.1 s vs. 0.2 s per step):
    • how fast your language is (Python vs. C),
    • how fast your libraries are (NumPy loops in C),
    • whether you can cache results or compute in parallel.
  • Note: there are also \(o\), \(\omega\), \(\Omega\), \(\theta\), \(\Theta\), and more. We only use big O in this course.

(Bonus Slide) 📈 Where the doubling rule comes from

Compare the runtime at \(2n\) with the runtime at \(n\): \(\dfrac{g(2n)}{g(n)}\).

  • \(O(1)\), constant: \(\dfrac{g(2n)}{g(n)} = \dfrac{c}{c} = 1\) → same runtime; \(n\) never enters the formula.
  • \(O(n)\), linear: \(\dfrac{g(2n)}{g(n)} = \dfrac{2n}{n} = 2\) → 2× (the notify loop: twice the drivers, twice the work).
  • \(O(n^2)\), quadratic: \(\dfrac{g(2n)}{g(n)} = \dfrac{(2n)^2}{n^2} = \dfrac{4n^2}{n^2} = 4\) → 4× (the matching loop).
  • \(O(n^3)\), cubic: \(\dfrac{g(2n)}{g(n)} = \dfrac{(2n)^3}{n^3} = \dfrac{8n^3}{n^3} = 8\) → 8×.
  • \(O(n^k)\), polynomial: \(\dfrac{g(2n)}{g(n)} = \dfrac{(2n)^k}{n^k} = \dfrac{2^k n^k}{n^k} = 2^k\) → \(2^k\)×.

(Bonus Slide) 📈 The logs and the exponential

  • \(O(\log n)\), logarithmic: here the difference is the interesting part, not the ratio. \[g(2n) - g(n) = \log_2(2n) - \log_2 n = \log_2\frac{2n}{n} = \log_2 2 = 1\] → + a constant: doubling \(n\) adds one more step, not one more of everything.
  • \(O(n \log n)\), linearithmic: \[\frac{g(2n)}{g(n)} = \frac{2n \log_2 (2n)}{n \log_2 n} = \frac{2n(\log_2 n + 1)}{n \log_2 n} = 2\left(1 + \frac{1}{\log_2 n}\right)\] → a bit more than 2×, and the extra part shrinks as \(n\) grows.
  • \(O(2^n)\), exponential: \[g(2n) = 2^{2n} = (2^n)^2 = \big(g(n)\big)^2\] → the runtime is squared, not multiplied by a constant.